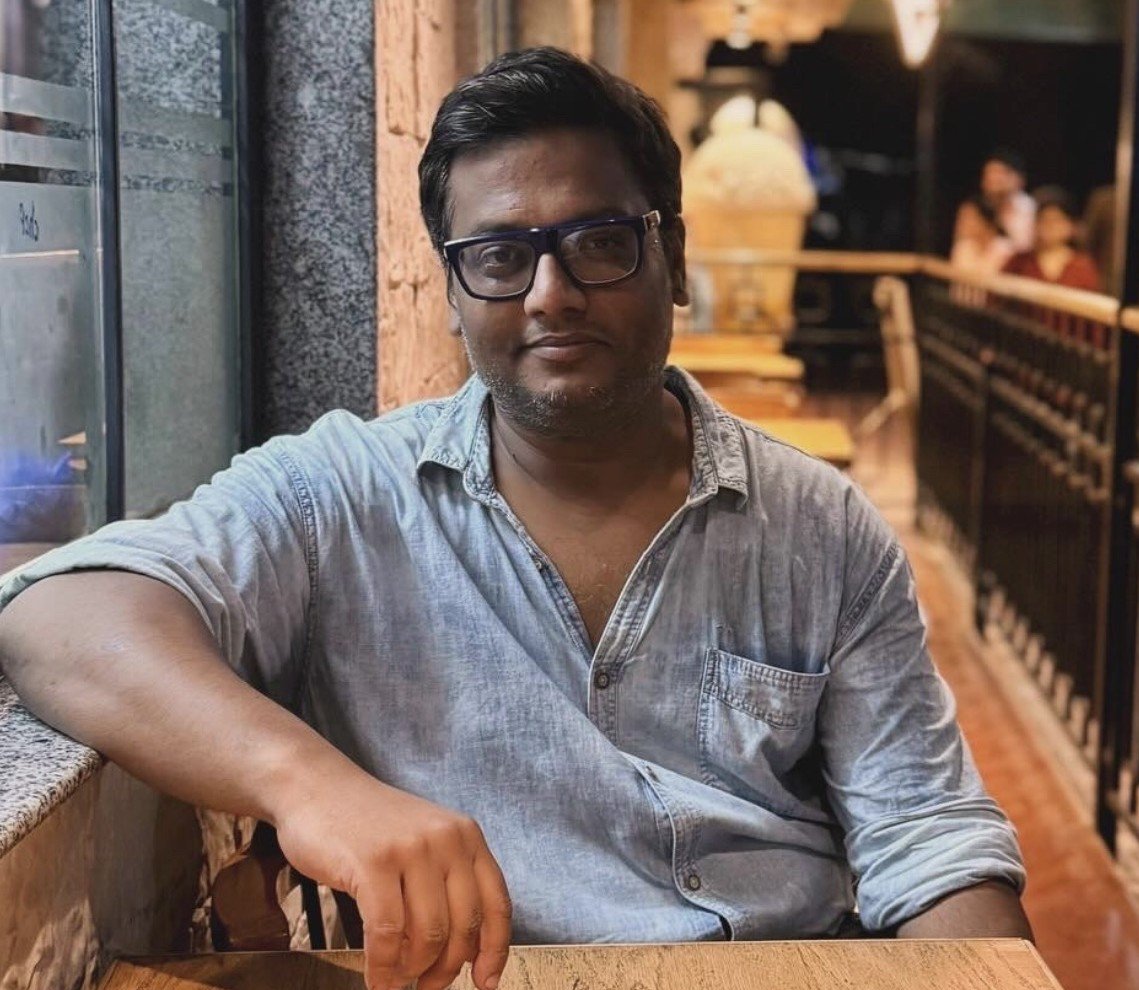
Artificial Intelligence will gain offensive capabilities at cybersecurity in near future with frontier models doubling their performance as banks, telecoms, energy sector and critical infrastructure become key targets for AI-assisted/AI-autonomous cyberattacks, opined Dan Lahav, co-founder and CEO of Irregular, an AI security company partnering with top frontier AI labs.
Lahav’s warning comes amid recent incidents of frontier AI models autonomously hacking into third party companies as well as bad actors using AI tools for coordinated cyberattacks.
In a blogpost, Lahav opined that AI models are scaling offensive capabilities faster than we can imagine with rampant cost-cutting ensuring that even open-weight AI models are just months away from offensive-grade capability levels of frontier models like Claude Mythos and GPT-5.6 Sol.
𝗧𝗵𝗲 𝗘𝗻𝗱-𝗦𝘁𝗮𝘁𝗲 𝗙𝗮𝗹𝗹𝗮𝗰𝘆: 𝗪𝗵𝗲𝗿𝗲 𝗜𝘀 𝗔𝗜 𝗦𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝗚𝗼𝗶𝗻𝗴?
Frontier AI models had a giant performance gain in coding in the Fall of 2025
Then with cybersecurity in April
This is now happening with open-weight models
We are optimistic about the… pic.twitter.com/lMeex2k0mB
— Dan Lahav (@dan_lahav) August 17, 2026
Giving a comparative analysis, Lahav said that in April 2026, the best-performing AI models could occasionally solve security challenges that too at a cost of roughly $2000. Within the next four months, the cost went down to $20 and success rate reached 100% for the same AI models.
“At least over the next two years, frontier models will continue to roughly double their performance and effective autonomous work horizon every six months across many important offensive cyber tasks…Further in the future, the most consequential campaigns will likely concentrate on high-value targets: banks, telecoms, energy companies, other critical infrastructure, and large organizations holding valuable data or assets,” said Lahav in his essay The End-State Fallacy: Where is AI Security Headed?
Irregular, a Tel-Aviv based AI security company has partnered with OpenAI, Anthropic, Meta and Google for red-teaming and evaluation benchmark for the frontier AI models. The company was recently involved in evaluation of AI models of Anthropic and Meta that had autonomously hacked into different organizations when provided internet access.
Lahav opined that while the end goal of frontier AI systems must be fool-proof defensive capabilities, the journey to reach that stage will result in AI increasing its offensive capabilities with bad actors utilizing it against cyber defenders.
Proposing Differential Defensive Cyber Acceleration (DDCA) Lahav said that the need of the hour is to develop a pragmatic strategy that disproportionately benefits cyber defenders compared to the rise of offensive capabilities of AI systems.
“DDCA is a strategy for altering the course of that sequence: deliberately shaping the development, diffusion, and deployment of AI security capabilities so that protective capabilities mature and reach defenders before corresponding offensive capabilities can overwhelm them,” said Lahav.
Also Read: Anthropic Raises Misalignment Risk to “Low,” Keeps “Somewhat More Capable” Model 2 Internal